|
Minsu Kim I'm a PhD student studying computer vision at Yonsei University, advised by Prof. Seon Joo Kim. My research interests lie primarily in 3D computer vision, and I lead the 3D vision team in our lab. More recently, I have also been exploring robot learning and its connections to spatial intelligence. |

|
ResearchMy research focuses on spatial intelligence, spanning 3D reconstruction, human motion understanding, and 3D scene understanding. More recently, I have been exploring how to extend spatial intelligence toward vision-language reasoning and physical AI, including embodied perception and robot learning. |
News[2026.09] Two papers, RelationVGGT and VODA, accepted in NeurIPS 2026. [2025.10] New paper out! SceneAdapt [2025.06] ExploreGS accepted in ICCV 2025. |
Publications |
|
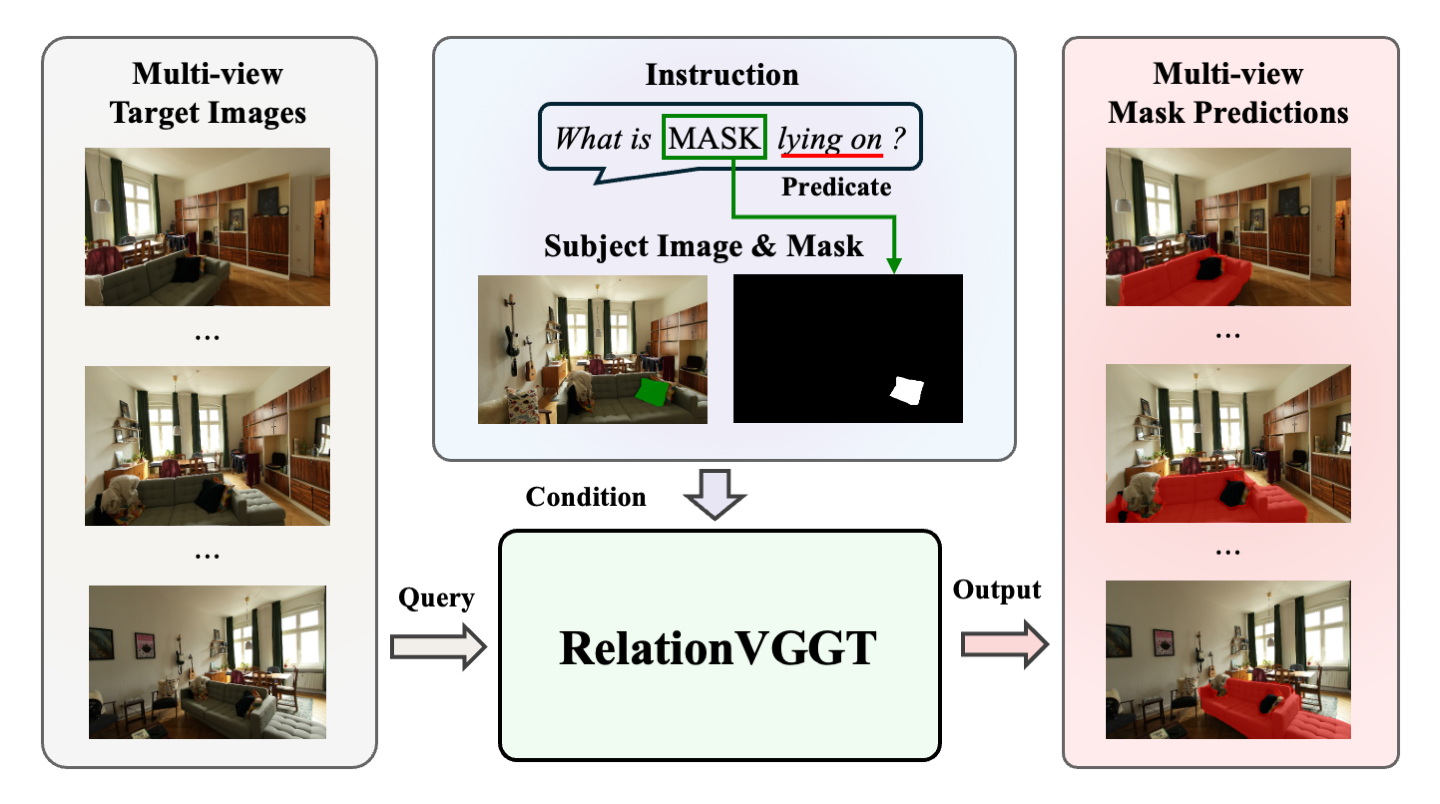
RelationVGGT: Visual Geometry Transformers for 3D Spatial Relation Segmentation
Minsu Kim1, Jaesung Choe2, Jiwoo Lee1, Yu-Chiang Frank Wang2, Seon Joo Kim1 1Yonsei University, 2NVIDIA Academic collaboration with NVIDIA Taiwan NeurIPS, 2026 project page / arXiv TL;DRGiven a subject mask in one view and a relational query such as "resting on", RelationVGGT segments the target object in every other view without being told its category. It runs in a single forward pass on unposed images, requiring neither per-scene optimization nor known camera poses. |
|
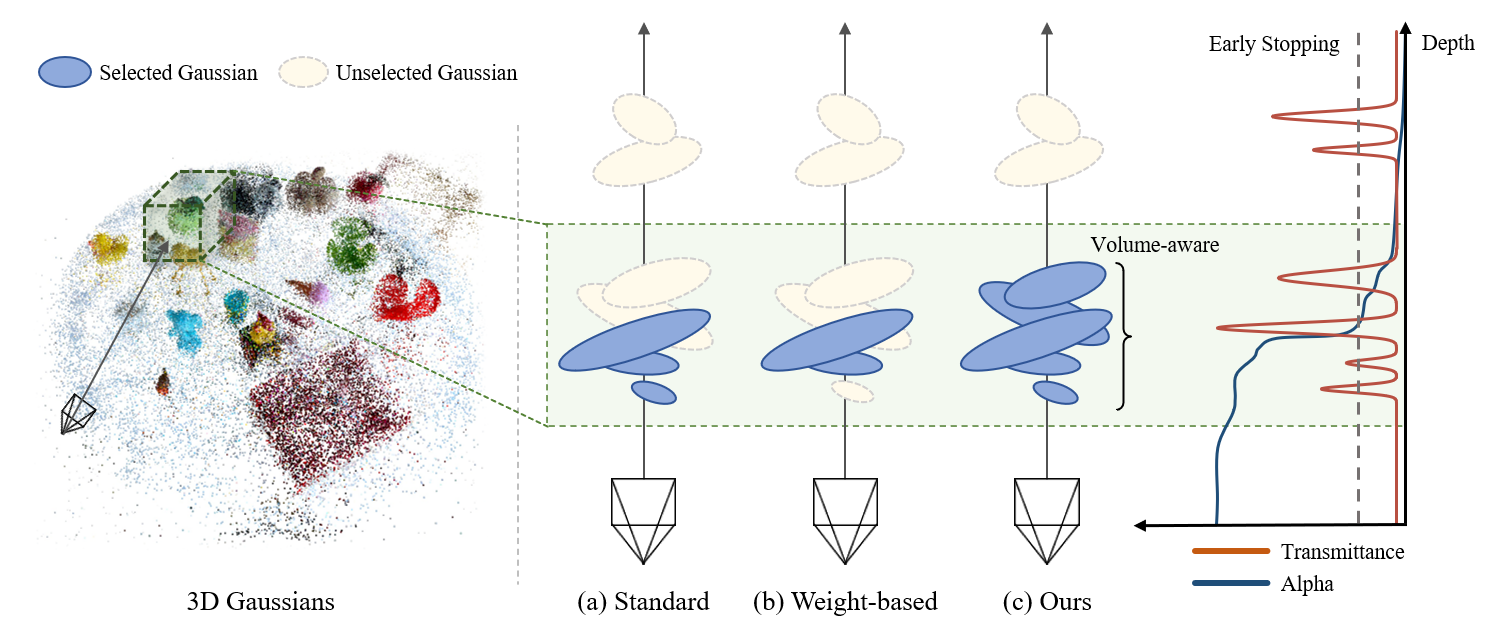
The Mask Is Not the Object: Volumetric Supervision for 3D Gaussian Segmentation
Jeonghwan Cho, Minsu Kim, Junyoung Hong, Seon Joo Kim NeurIPS, 2026 project page TL;DR3DGS segmentation renders accurate masks but selects an incomplete set of object Gaussians. VODA is a plug-and-play objective that directly supervises every Gaussian in an object's depth cluster, and Removal-3D benchmarks whether removing them actually changes the scene in 3D. |
|
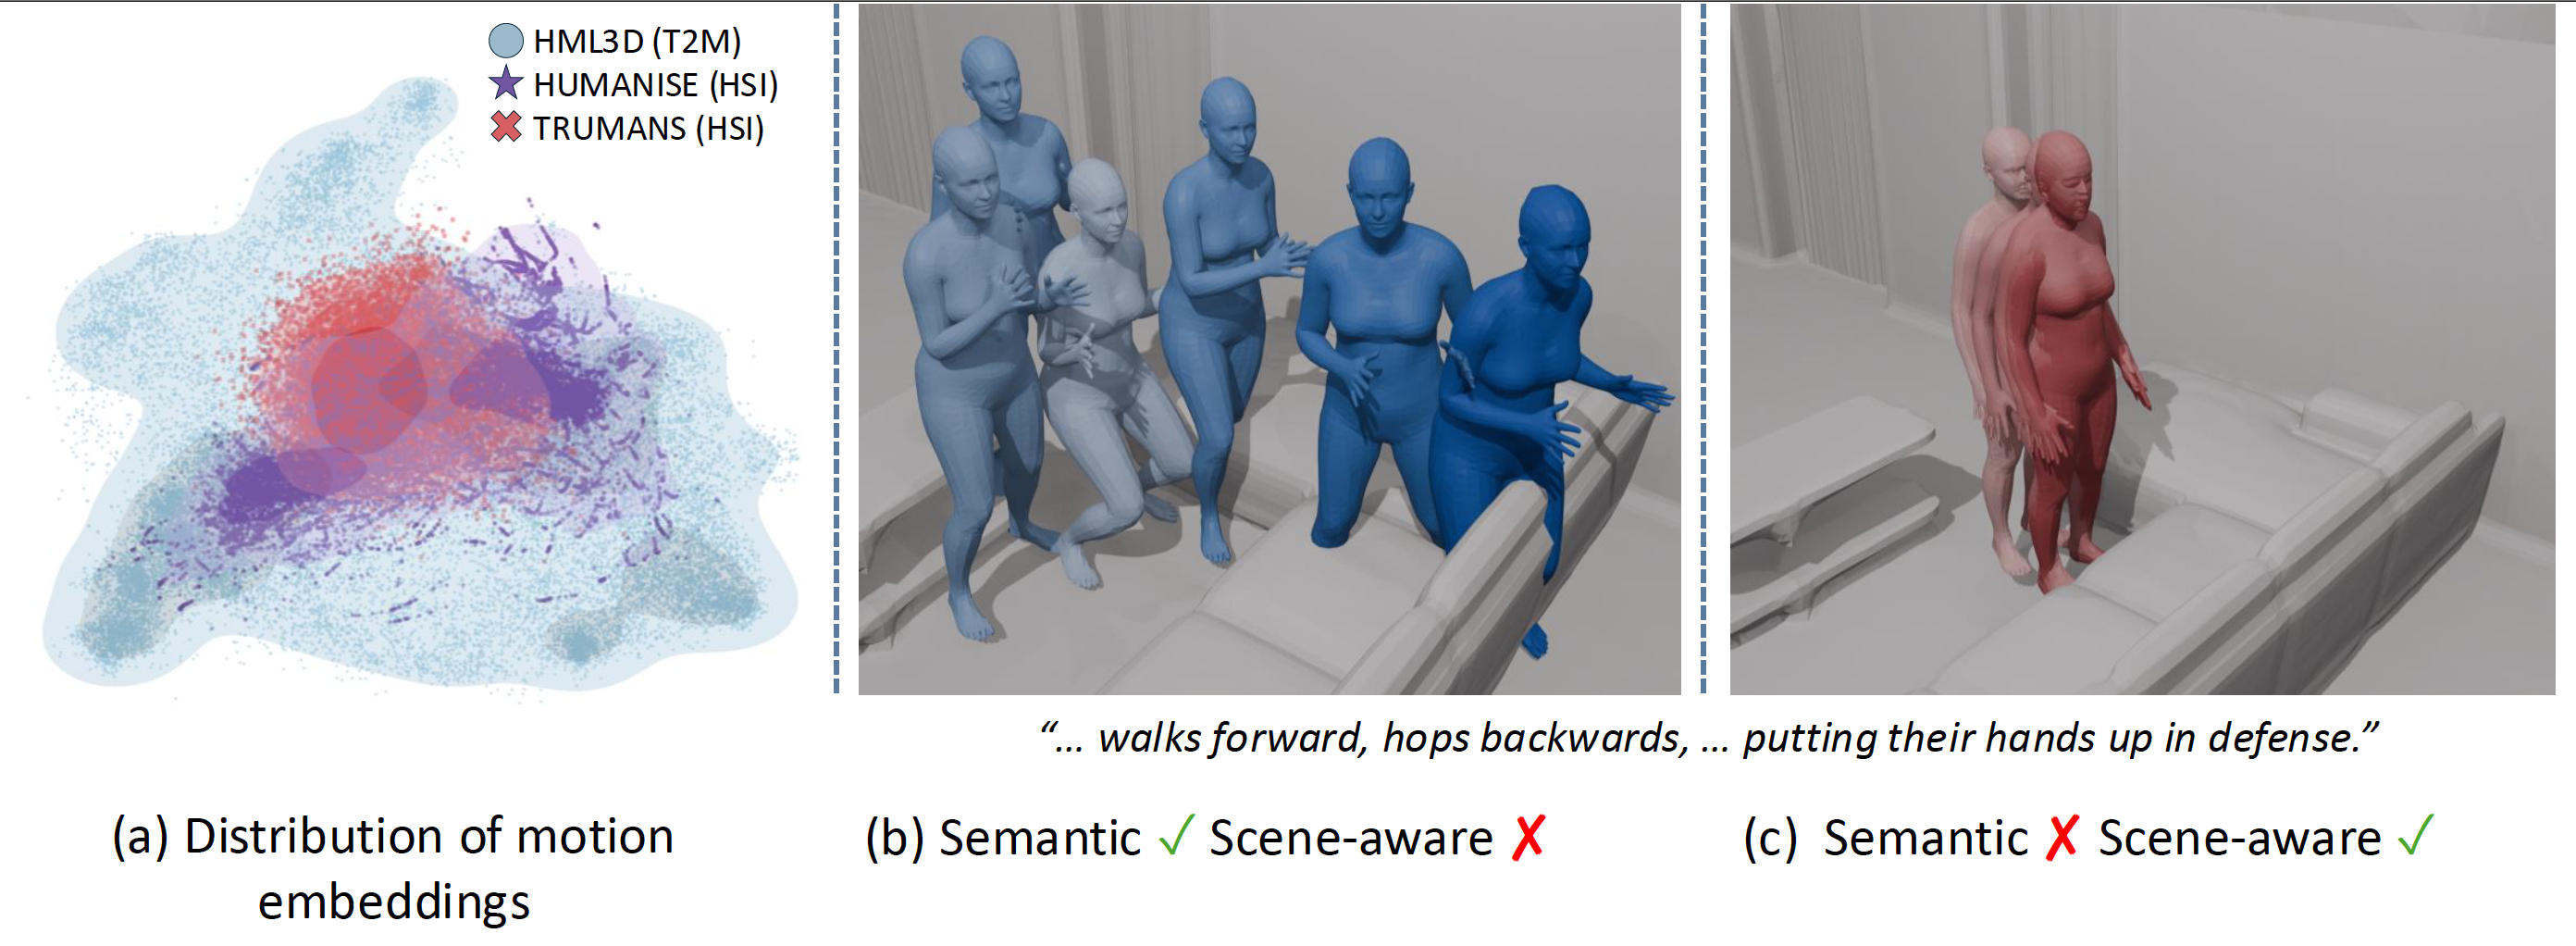
SceneAdapt: Scene-aware Adaptation of Human Motion Diffusion
Jungbin Cho*, Minsu Kim*, Jisoo Kim, Ce Zheng, Laszlo A. Jeni, Ming-Hsuan Yang, Youngjae Yu, SeonJoo Kim, preprint, 2025 project page / arXiv TL;DRGenerating diverse motions that also respect scene constraints is challenging due to the scarcity of paired datasets. SceneAdapt bridges separate scene–motion and text–motion datasets via motion inbetweening to inject scene awareness into text-to-motion models. |

|
ExploreGS: Explorable 3D Scene Reconstruction with Virtual Camera Samplings and Diffusion Priors
Minsu Kim, Subin Jeon, In Cho, Mijin Yoo, Seon Joo Kim ICCV, 2025 project page / arXiv / code TL;DRCan we freely explore reconstructed scenes from casually captured videos whose viewpoints are not sufficient? ExploreGS introduces a novel pipeline that samples virtual viewpoints to cover missing content and leverages diffusion priors, enabling explorable 3D scenes. |

|
Hierarchically Structured Neural Bones for Reconstructing Animatable Objects from Casual Videos
Subin Jeon, In Cho, Minsu Kim, Woong Oh Cho, Seon Joo Kim ECCV, 2024 project page / arXiv / code TL;DRWe propose a new framework for creating and easily manipulating 3D models of arbitrary objects using casually captured videos. Our core ingredient is a novel hierarchy deformation model, which captures motions of objects with a tree-structured bones. |